Foundations for TPU development
Build with your preferred framework and diagnostic tools to drive peak performance
 PyTorch on Cloud TPUTrain, fine-tune, and serve models using native PyTorch semantics, torch.compile, and open-source ecosystem tools on Cloud TPUs.Docs
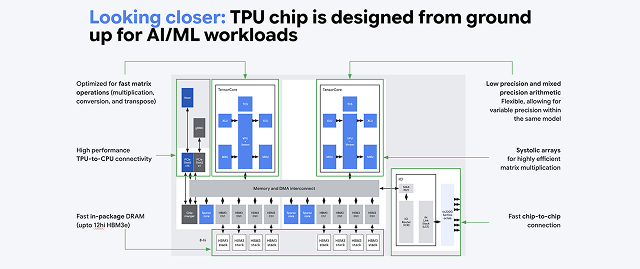
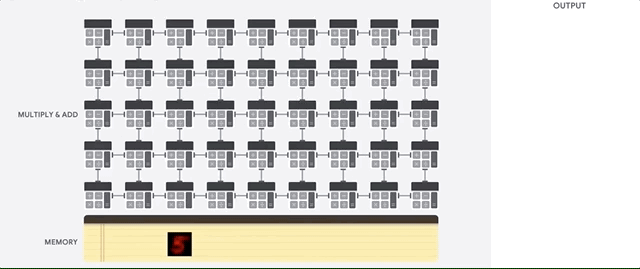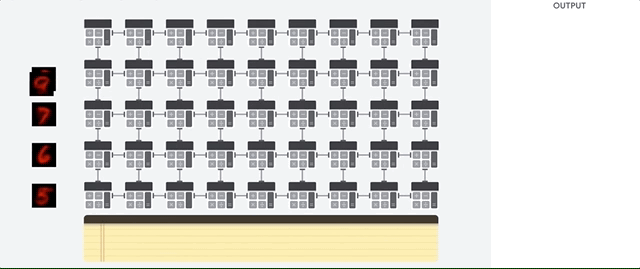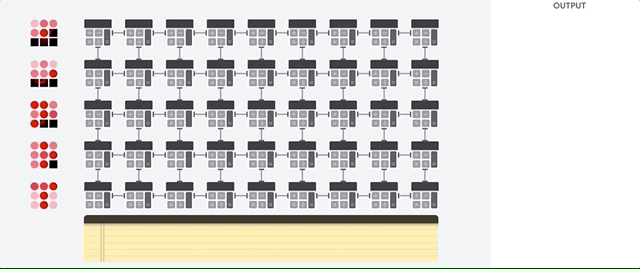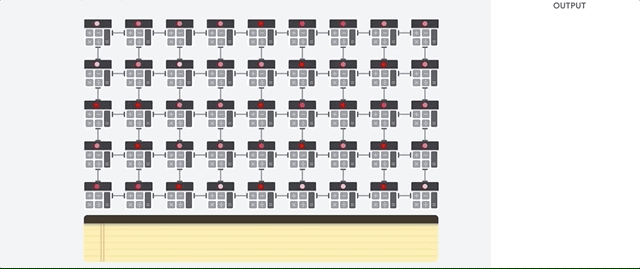 Learn about TPU architectureTensor Processing Units (TPUs) are Application-Specific Integrated Circuits (ASICs) designed by Google to accelerate machine learning workloads. Google Cloud makes TPUs available as a scalable resource.Tutorial
Accelerate production inference on TPUs
Deploy high-throughput, low-latency workloads using vLLM and optimized TPU serving stacks
 New vLLM and SGLang Inference Engines on TPUServe open-weight LLMs and MoEs at scale with native PyTorch backends for vLLM and SGLang, custom Pallas kernels, and TPU Sync.Blog
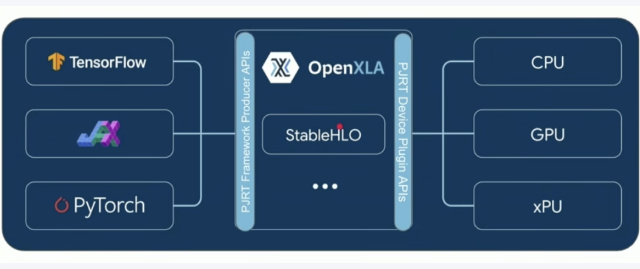
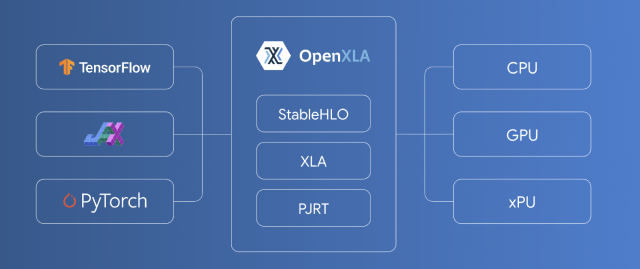
 Announcing XLA Serving EngineWe are excited to announce the launch of XLA Serving Engine (XSE), a general-purpose model export and inference runtime for the OpenXLA ecosystem, open-sourced under the Apache 2.0 license.Blog
 llm-d 1.0: OS Distributed Inference on GKECoordinate fleets of vLLM-TorchTPU and SGLang-TorchTPU servers on Kubernetes with prefix-aware routing and disaggregated serving.Blog
 Multimodal Embedding Inference on Cloud TPULearn how we bring high-dimensional vector pooling models to TPU hardware topologies to serve next-generation embedding models in production.Blog
 Optimizing Qwen 3.5-397B MoE on IronwoodThis technical report details how we systematically applied a global optimization playbook to Qwen 3.5 MoE on Ironwood TPUs.Blog
 Gemma 4 is now available on vLLM TPUvLLM introduces support and community recipes for Gemma 4, with Day 0 support on Google TPUs.Guide
 Inference recipes for TPUGet recipes to run the latest open weight models on Ironwood with vLLM, including Qwen3 and GPT-OSS.Code
 vLLM for LLM inferenceLearn the essential skills to design and implement efficient AI inference solutions using Google Cloud's specialized hardware and popular open-source frameworks.Course
Scale model pre-training on TPUs
Achieve higher training throughput using JAX, PyTorch, and Keras on TPUs
 How to scale your modelTraining LLMs often feels like alchemy, but understanding and optimizing the performance of your models doesn't have to. This book aims to demystify the science of scaling language models.ebook
 Build an LLM with JAXBuild a GPT-2 style language model with 20 million parameters from scratch using JAX, the open-source library behind Google’s Gemini, Veo, and Nano Banana models.Course
 MaxTextHigh performance, highly scalable, open-source LLM library and reference implementation written in pure Python/JAX and targeting Google Cloud TPUs and GPUs for training.Tutorial
 A developer’s guide to training with Ironwood TPUsThis technical overview explores the specific methods and tools within the JAX and MaxText ecosystems designed to refine training efficiency and reach peak performance on Ironwood hardware.Guide
 Elastic training with MaxTextWhat happens when one machine dies in the middle of a multi-node training run? In this article we'll explore a possible answer, called elastic training, using the JAX AI stack (MaxText and Pathway) and on Cloud TPUs.Blog
 Inside the optimization of FP8 training on IronwoodGoogle’s Ironwood chips are our first TPUs to support 8-bit floating point precision, helping to accelerate AI training and inference by reducing memory usage and increasing throughput.Blog
Optimize post-training on TPUs
Efficiently customize and align open models for high-performance serving and deployment
TPU workload orchestration
Simplify cluster management and scale your workloads efficiently
 Cloud Pathways is now GAWe are thrilled to announce the general availability (GA) of Cloud Pathways (Pathways on Cloud) on Google Kubernetes Engine (GKE) as a core runtime pillar of the Google Cloud AI Hypercomputer.Blog
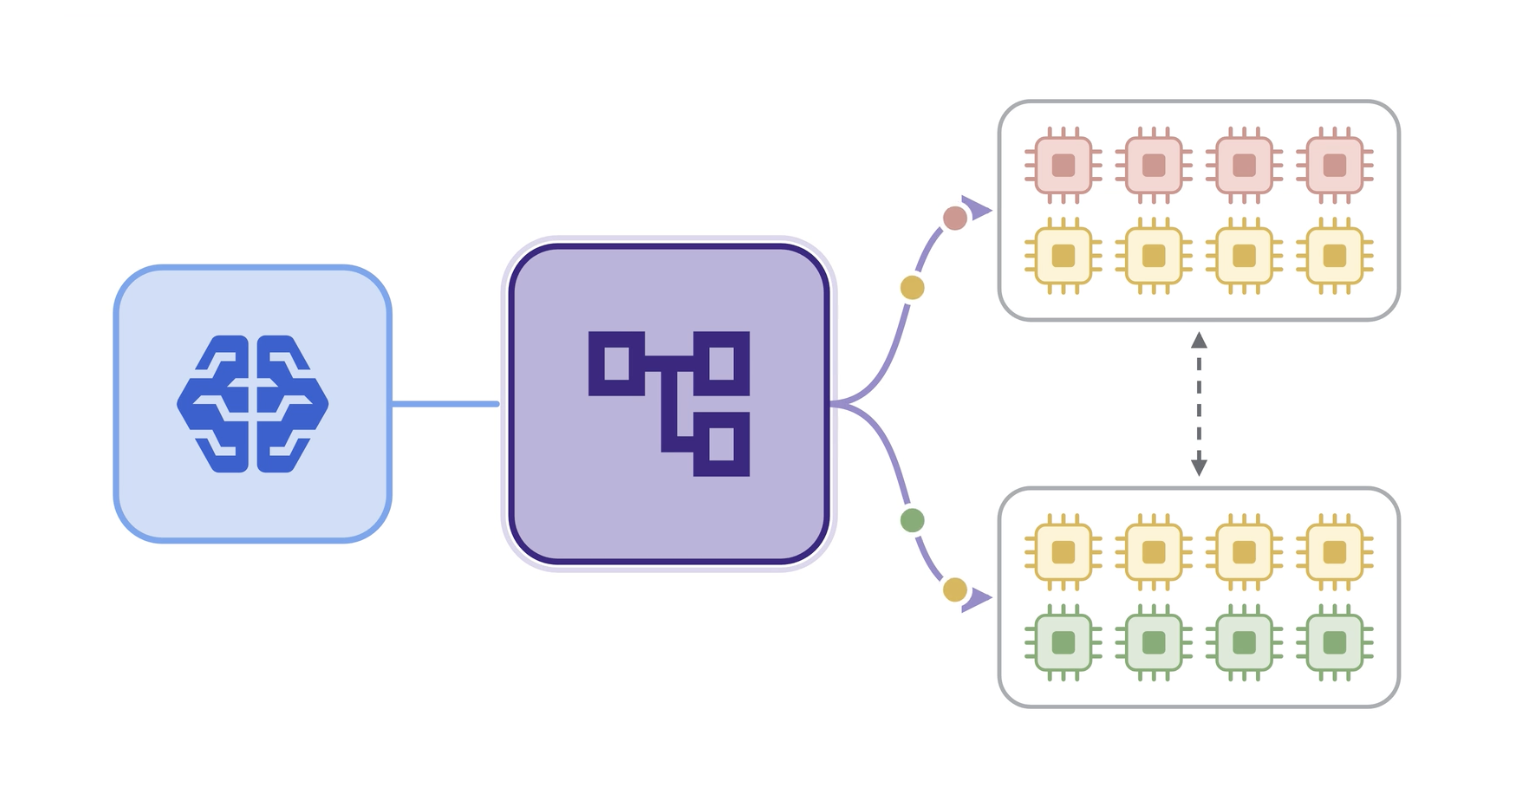 Single-controller training with PathwaysLearn how Pathways addresses the coordination challenge by introducing one client that describes the whole computation as a graph.Blog
 Scaling PyTorch on TPUs with RayOrchestrate multi-slice training, Ray Data prefetching, and distributed RL post-training (VeRL) natively on Cloud TPUs with Anyscale and Ray.Blog
Profile and debug TPU workloads
Uncover bottlenecks and optimize your model’s execution
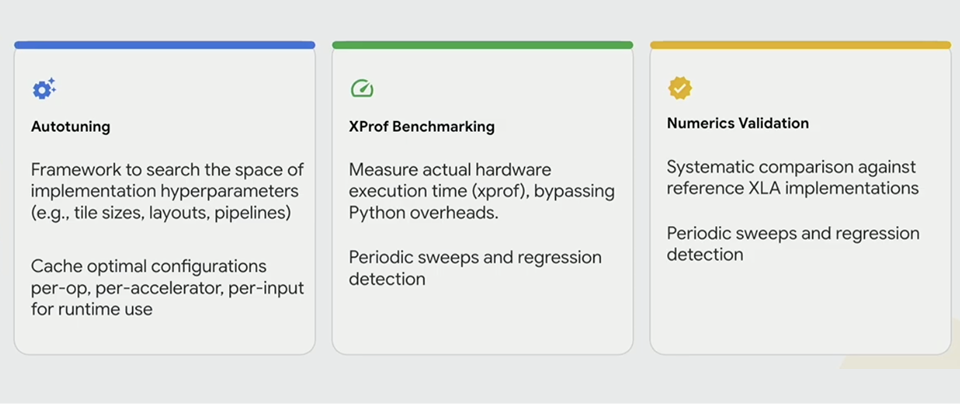
 Microbenchmarks for evaluating TPU performanceUse our new microbenchmark suite to evaluate TPUs for sample workloads.Guide
 Deep Kernel profiling with XProfIntroducing the Kernel Profiling suite in XProf—a low-level hardware debugging suite engineered specifically for Pallas kernel authoring and optimization on Google TPUs.Blog
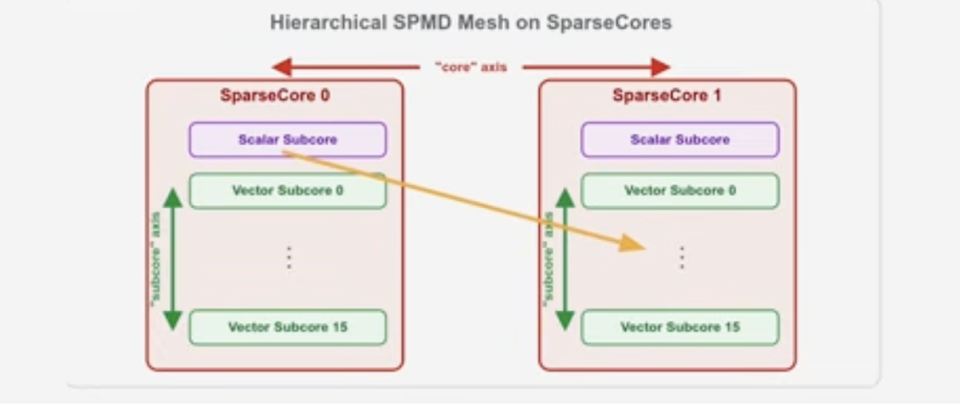
 Advanced TPU optimization with XProfIntroducing three advanced capabilities designed to provide instruction-level insights: Continuous Profiling Snapshots, the Utilization Viewer, and LLO Bundle Visualization.Blog
 Supercharge ML performance with XProfLearn how XProf, our core ML profiler, pairs with the new Cloud Diagnostics XProf library to easily identify model bottlenecks.Blog
Secure and scale TPU workloads
Design secure, high-performance network architectures for your AI workloads
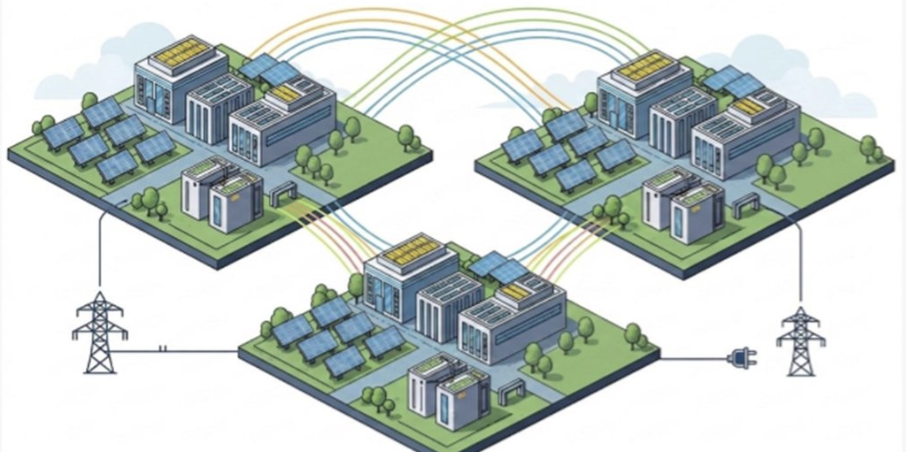 Evolving Google’s data center networks for the AI eraHow Google created an end-to-end, vertically integrated AI technology stack that comprises everything from chips to systems, to platforms and application and agentic ecosystems.Blog
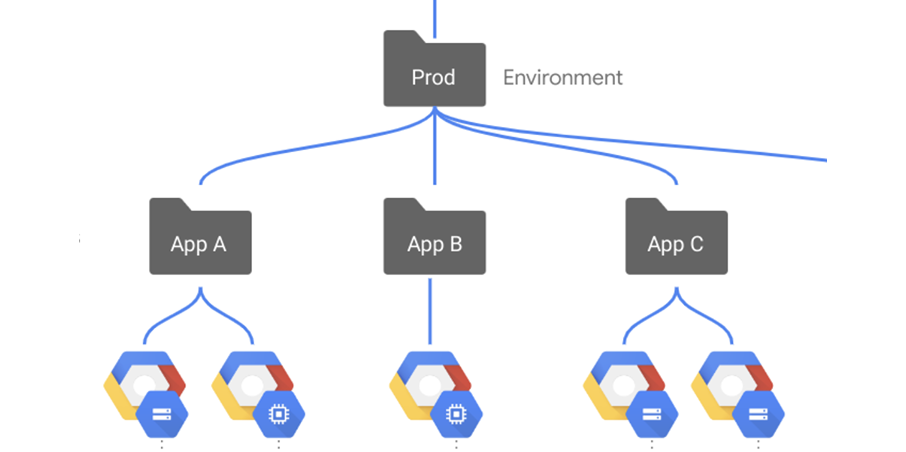 Data encryption for AI WorkloadsLearn about additional ways to encrypt your data when using Cloud Storage along with TPUs for AI workloads.Guide
 Using VPC Service ControlsGet hands-on tips, guidance on how to set up a service perimeter using VPC Service Controls in the Google Cloud console.Guide
Community contributions
Resources and code samples from our developer community
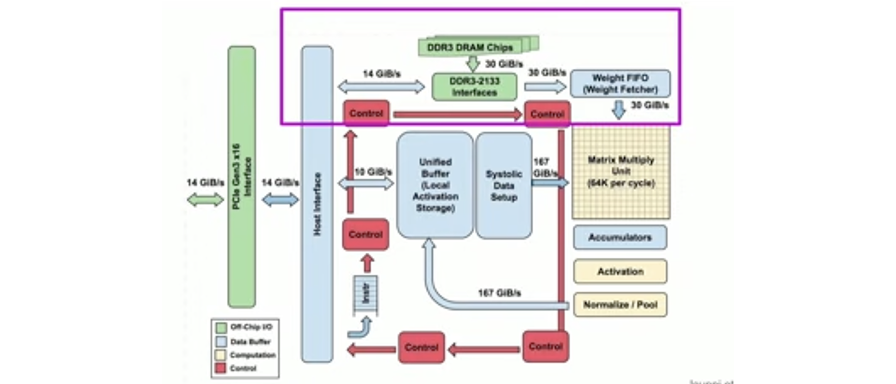
 Tuning Pallas from scratchA practical walkthrough on writing, profiling, and auto-tuning custom TPU kernels.Guide
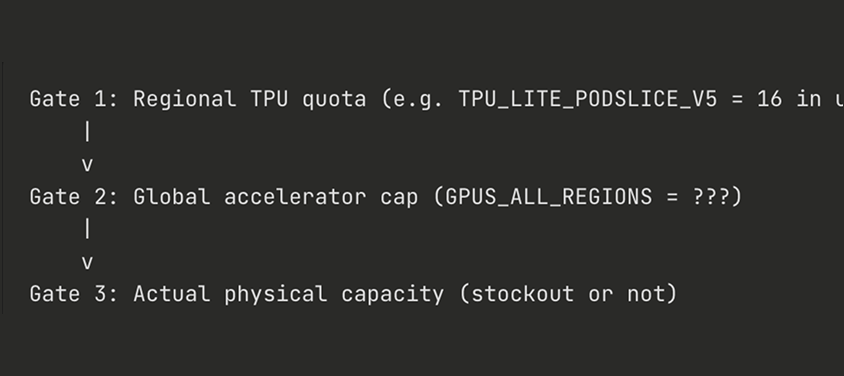 Elastic LLM Inference on TPUsAn infrastructure guide for autoscaling an elastic LLM serving system on GKE with vLLM.Guide
 From Google TPU to VillageFine-tuning medical AI on TPUs, quantized for offline edge inference hardware.Guide
TPU developer resources
Explore official documentation, workload recipes, and the latest technical updates for Cloud TPUs
- TorchTPU TutorialsDive into official quickstarts, eager and compiled execution guides, custom Pallas kernel tutorials, and API references on Read the Docs.Guide
- TPU documentationLearn how to access and use TPUs on Google Cloud.Guide
- Plan your Cloud TPU resourcesDiscover how you can request Cloud TPU VM capacity based on your needs.Guide